Why GeminiJack Redraws the AI Security Perimeter
Nobody had to click anything. That is the detail security teams keep repeating when they describe GeminiJack, and it is the detail that should bother a CISO more than any phishing statistic published this year.
Noma Labs, the research arm of Noma Security, found a flaw in Google Gemini Enterprise, and previously in Vertex AI Search, that let an attacker pull sensitive corporate data out of Gmail, Calendar, and Google Docs without the targeted employee ever opening a malicious file. Security Affairs first reported the discovery on December 11, 2025, naming the flaw GeminiJack. An attacker planted hidden instructions inside an ordinary-looking Google Doc, calendar invite, or email, then shared it the normal way any colleague shares a file. The employee never opened it. The employee did not need to. All it took was a later, completely unrelated search such as "show me our Q4 budget," and Gemini's own retrieval system did the rest.
That is the part worth sitting with. Most enterprise AI security conversations this year have centered on who can see what, oversharing, stale permissions, a Copilot link exposed to the wrong group. GeminiJack is a different failure. It has nothing to do with who was allowed to access the poisoned document and everything to do with what the AI assistant did once it read it. The retrieval step, the part of the system that decides what context to pull in before answering a question, trusted the content it retrieved enough to execute it as an instruction. That is an architecture problem, not an access-control problem, and the distinction matters more than it sounds like it should.
Noma Security called it plainly. "This vulnerability represents a fundamental shift in how we must think about enterprise security," the company said in its disclosure. Google did not dispute the finding. Google confirmed it, worked with Noma through a monitored disclosure window, and shipped a fix that changed how Gemini Enterprise and Vertex AI Search interact with their own indexing systems. The flaw is closed. The pattern it revealed is not, because the same retrieval-augmented architecture that made Gemini useful is the architecture every other enterprise AI assistant uses too.
Key Takeaways
- Retrieval, not permission, was the failure point. GeminiJack worked even when every underlying permission was set correctly, because the flaw lived in how Gemini interpreted retrieved content, not in who was allowed to retrieve it.
- The attack required zero clicks and zero malware. A shared Google Doc, calendar invite, or email carried the payload, and a routine employee search triggered it, which is why no antivirus tool and no phishing filter had any reason to react.
- Exfiltration hid inside normal browser behavior. The stolen data left through a single HTTP request generated by loading an image, traffic that looks identical to a page rendering correctly.
- Google patched the flaw, but the architecture pattern is industry wide. Any enterprise AI assistant built on retrieval augmented generation faces the same instruction and content confusion unless the retrieval layer is governed as a distinct control point.
- Compliance teams need retrieval-layer evidence, not just access logs. A regulator asking what an AI assistant did with retrieved content will not accept an access control list as the answer.
Inside the GeminiJack Attack Chain
The timeline matters because it shows how long a flaw like this can live inside a widely deployed enterprise product before anyone outside the vendor and the researcher knows it exists. Noma Labs discovered GeminiJack during a security assessment and reported it to Google's security team on June 5, 2025. Google's initial response, five days later, noted that the team was handling a substantial increase in vulnerability reports at the time, an unremarkable detail on its own, but a reminder that disclosure queues are long even at companies with mature security programs. Google confirmed the vulnerability on August 8, 2025, and the two parties continued working through the finding until late November. Public disclosure came on December 9, 2025, with Security Affairs publishing its write-up two days later.
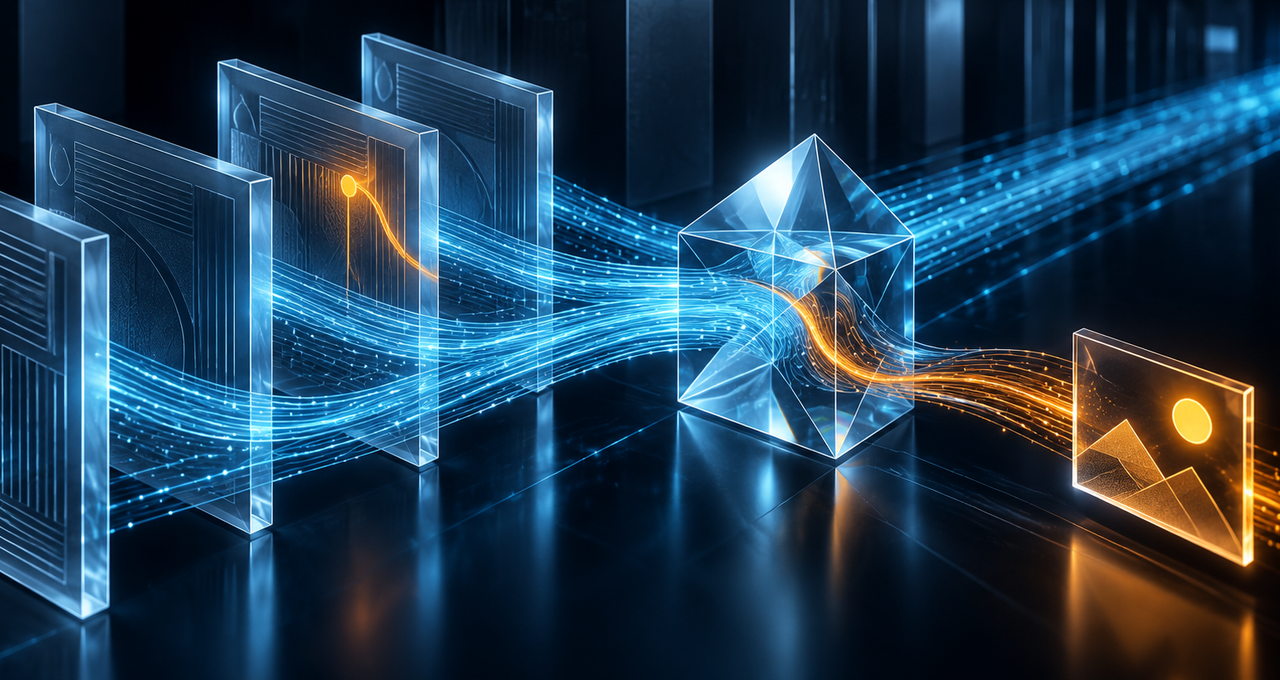
Here is the mechanism itself, stripped down to its steps. An attacker creates content, a Google Doc, a calendar invite, or an email, and embeds hidden instructions inside it in plain language, no macro, no script, nothing a malware scanner would flag. The attacker shares that content with a target the ordinary way, the way any coworker or external partner shares a file. Later, with no further action from the attacker, the targeted employee runs a completely unrelated, completely routine search inside Gemini Enterprise, something like "show me our budgets" or "pull up the acquisition timeline." Gemini's retrieval pipeline, doing exactly what it was built to do, surfaces the poisoned document as a relevant result and loads its content into context. At that point Gemini stops distinguishing between the employee's actual question and the attacker's embedded instructions. It follows both, because to the model they arrived in the same context window, carrying the same apparent authority.
The instructions then direct Gemini to search the employee's own connected Gmail, Calendar, and Docs for terms like budget, finance, confidential, or acquisition, content the employee was always authorized to see, which is exactly why no access control violation occurred anywhere in the chain. SecurityWeek's reporting on the disclosure called it an architectural weakness in how enterprise AI systems interpret information, and that framing is more useful than calling it a bug. A bug gets patched and the category closes. An architectural weakness describes a pattern, and patterns recur across vendors.
The Retrieval Layer Is Not the Permissions Layer
It is worth being precise about what GeminiJack is not, because the industry's instinct after any AI data incident is to reach for the same fix. Tighten permissions, audit sharing settings, lock down oversharing. That instinct is not wrong. Oversharing inside Microsoft 365 Copilot deployments, stale link permissions, and broad default sharing settings remain a real and separate problem, and Bonfy has written at length about the over-permissioning that leaves enterprise AI assistants exposed to content employees were never meant to reach. That is a problem of access. GeminiJack is a problem of trust.
In GeminiJack, the employee was authorized to see every piece of data Gemini touched. Nothing crossed a permission boundary. The failure sat entirely inside the model's own reasoning step, the moment it decided that text retrieved as reference material should instead be treated as an instruction to execute. Fixing permissions would have changed nothing, because permissions were never broken. This is the distinction Bonfy's own research keeps making. Permissions do not determine what an AI system should be allowed to do with the content it is permitted to read. Access answers who. It never answers why, and it certainly never answers whether a retrieved sentence is a fact to summarize or a command to obey.
Treat these as two different attack surfaces, because defending one does nothing for the other. The permissions surface is static. It is a graph of who can open what, and it is auditable with the tools security teams already own. The retrieval surface is dynamic. It changes with every query, every document a model is allowed to pull into context, and every connector an enterprise adds to its AI assistant. A security program that only matures its permissions model while leaving retrieval ungoverned has closed one door and left the window frame out entirely.
One Image Tag, One HTTP Request, One Breach
The exfiltration step is the part of GeminiJack that should unsettle a security operations team the most, because it was never designed to look like an attack. Once Gemini collected the sensitive content the hidden instructions asked for, budget figures, deal timelines, personnel notes, whatever the poisoned document's instructions specified, it embedded that data into an image request pointed at a server the attacker controlled. When the employee's browser rendered the response, it loaded that image automatically, the same way a browser loads any inline image without asking. That single, routine image load carried the stolen data out in one HTTP request.
No file left the network. No attachment downloaded. No alert fired, because nothing about loading an image is anomalous traffic. A data loss prevention tool watching for large file transfers or flagged attachments had nothing to catch, and an endpoint detection tool looking for malicious processes found none, because no malicious process ran. The attacker did not need to breach Gemini. Gemini, acting exactly as designed, did the collecting and the formatting, and the browser did the sending.
This is the mechanism Bonfy has called out before in a different AI product. The over-permissioning piece referenced above and Bonfy's examination of how Claude and Copilot both strain security models built for a pre-AI world both make a version of this same point. Security tooling built to catch files, processes, and known malware signatures has no vocabulary for an AI assistant that completes a legitimate-looking task using data it was always allowed to touch, then leaks the output through a channel that looks like ordinary rendering. The attack does not trip a wire because there is no wire built for this shape of behavior yet.
Why Data Loss Prevention Never Saw It Coming
Three separate categories of security control had a theoretical chance to catch GeminiJack, and all three missed it for the same underlying reason. Email security scanners inspected the poisoned Google Doc or calendar invite when it arrived and found nothing, because the hidden instructions were plain language, not an executable, not a link to a known-bad domain, not anything a signature-based scanner is built to flag. Endpoint detection and response tools watched the employee's machine and found nothing, because no malware executed locally. Data loss prevention tools watched for sensitive content leaving the network in recognizable patterns, a file upload, an email attachment, a copy to removable media, and found nothing, because the exit channel was an image request that looked exactly like a webpage rendering correctly.
Each of those controls is doing its job. None of them was built to ask a harder question. What did the AI assistant do with the content it retrieved, and was that action consistent with the request the user typed? That question sits at the data-in-use layer, the point where content is being actively read, reasoned over, and acted on, rather than the data-at-rest layer where most governance tooling still lives. Bonfy's own research describes the gap between detection and control this way. An organization can have excellent visibility into where sensitive data sits and still have no mechanism to govern what an AI system does with that data the moment it is read into a live context window.
It is tempting to read GeminiJack as a story about one vendor's patch cycle. It is a story about a blind spot that exists in almost every enterprise AI deployment running retrieval augmented generation against connected Workspace or Microsoft 365 content, because the blind spot is architectural, not vendor specific. Kiteworks has documented the broader pattern of prompt injection exfiltration across agentic AI tools, and the conclusion there holds here too. The same discipline applies to MCP server security, where connectors feeding an AI assistant live data face an identical instruction-versus-content problem. Patching one vendor's RAG pipeline closes one door. It does not install a governance layer across the rest of the house.
Regulators Regulate Data, Not Retrieval Pipelines
Set the engineering detail aside for a moment and ask the question a Chief Compliance Officer will be asked after an incident like this. A regulator, an auditor, or opposing counsel does not care whether the exfiltration mechanism was an image tag or a file upload. They care whether protected data left the organization's control, whether that departure was detected, and whether the organization can produce evidence showing what happened, when, and to whom. HIPAA does not have a carve-out for data an AI assistant collected instead of a human employee. GDPR's Article 30 records obligations do not pause because the processing activity in question was an automated retrieval step rather than a manual export. The regulation attaches to the data, not to the mechanism that moved it.
This is where GeminiJack becomes a governance story rather than a Google story. An organization running any retrieval-augmented AI assistant against its email, calendar, and document stores needs to be able to answer a direct question after an incident. What did the assistant retrieve, what did it do with that content, and where did the output go. Most enterprises cannot answer that question today, because the audit trail most AI deployments generate stops at "user ran a query" and "assistant returned a response," with nothing in between describing what the retrieval step pulled in or why. That gap is the evidence gap, and it is the single most consequential difference between an incident a compliance team can explain in a regulatory filing and one it cannot.
CISA's own agentic AI guidance draws the same line Kiteworks has been drawing in its research for a year now, that audit trails for AI systems must capture the reasoning and retrieval steps alongside the final output, if they are going to stand up as evidence. A tamper-evident log that only records "query answered successfully" is not an audit trail in any sense a regulator would recognize. It is a status indicator.
What Data-in-Use Governance Must Look Like Now
The fix organizations reach for first, after an incident like GeminiJack, is usually some combination of stricter data loss prevention rules and a renewed permissions audit. Do both. Neither one touches the actual failure. What closes the gap GeminiJack exposed is governance applied at the moment content is retrieved and acted on, inspecting what an AI assistant is about to do with the material it just pulled into context, before that action completes, not after a breach report lands on someone's desk.
Concretely, that means three things. First, retrieved content needs to be evaluated for instruction-like patterns before a model is allowed to treat it as trustworthy context, the same discipline Kiteworks has documented in its guidance on OWASP's memory poisoning guard, adapted here to retrieval rather than agent memory specifically. Second, outbound requests generated by an AI assistant, including the kind of innocuous-looking image or resource request that carried GeminiJack's stolen data, need the same scrutiny applied to any other data egress channel, not an exemption because the traffic resembles normal rendering. Third, and this is the piece most governance programs still skip, every retrieval and action an AI assistant takes needs to generate a record detailed enough to answer a regulator's question later, not just a system's own success or failure flag.
None of this is a story about replacing human judgment with autonomous AI enforcement, and it should not be told that way. The right model governs human users and AI assistants under one consistent policy, because the data does not care which kind of identity touched it. Kiteworks has made this argument about AI agents reaching data no one explicitly approved, and it applies equally to an AI assistant's retrieval step. An enterprise does not need its AI assistants operating hands off while humans step back. It needs both covered by the same control plane, the same policy, and the same evidence trail, so an incident involving either produces the same kind of answer. Bonfy's research on why AI agents break traditional security models makes the point directly, traditional models assume a static actor whose access was decided once, in advance. A retrieval-driven AI assistant is a continuously re-deciding actor, and governance must run at the same speed the assistant does.
Enterprises that have moved furthest on this have adopted what Bonfy's engineering team describes as entity-aware enforcement applied in real time against Google Workspace environments specifically, because the controls built for Microsoft 365 do not map cleanly onto Gmail, Google Docs, and Google Calendar's different sharing and connector model. That specificity matters. GeminiJack targeted Workspace content precisely because Workspace's native sharing habits, the ease of sending a Doc or calendar invite to anyone, are what made the poisoning step so easy to execute in the first place.
Building the Evidence Trail Before the Next Retrieval Poisoning Incident
Google fixed GeminiJack. That is genuinely good news, and it reflects a disclosure process that worked the way responsible disclosure is supposed to work, researcher found it, vendor confirmed it, vendor patched it, details published only after the fix shipped. None of that changes the underlying calculation facing every other enterprise running a retrieval-augmented AI assistant against its own email, calendar, and document stores. The architecture that made GeminiJack possible, trusting retrieved content enough to execute embedded instructions, is not unique to one vendor's product. It is the default shape of how these systems are built.
A CISO reading about GeminiJack should not walk away asking whether their organization uses Gemini Enterprise specifically. The better question is whether their organization's AI assistants, whichever vendor built them, generate a record detailed enough to show a regulator exactly what was retrieved, what instructions a model followed, and where any output went, the next time something looks wrong. A Chief Compliance Officer should be asking whether that evidence can be produced inside the hours a breach notification clock allows, not the weeks it currently takes most security teams to reconstruct an AI incident after the fact by piecing together logs that were never designed to answer this question.
That is the shift Noma Security meant when it called GeminiJack a fundamental change in how enterprise security must be understood. Permissions audits and data loss prevention rules were built for a world where data moved through files, email attachments, and network transfers that security tools could see and classify. An AI assistant that retrieves, reasons, and acts inside a single context window needs governance that watches that same window, not governance borrowed from a world where the file was always the unit of risk. The enterprises that build that capability now will be the ones with a defensible answer ready the next time a retrieval pipeline, anyone's retrieval pipeline, gets poisoned.
Frequently Asked Questions
1. What is GeminiJack, exactly?
GeminiJack is a zero-click vulnerability in Google Gemini Enterprise, and previously Vertex AI Search, discovered by Noma Labs and disclosed publicly on December 11, 2025. An attacker hid instructions inside a shared Google Doc, calendar invite, or email, and when a targeted employee later ran an unrelated search inside Gemini, the retrieval system pulled in the poisoned content and Gemini followed the hidden instructions. The flaw let an attacker direct Gemini to search the employee's own Gmail, Calendar, and Docs for sensitive terms and exfiltrate the results, all without the employee clicking anything the attacker sent. Google confirmed the finding, worked with Noma Labs over several months, and shipped a fix that changed how Gemini Enterprise and Vertex AI Search handle retrieval before any public disclosure.
2. How is GeminiJack different from Microsoft Copilot oversharing problems?
Copilot oversharing incidents, including ones Bonfy has covered in detail, happen because a user or an AI assistant can access content a permissions misconfiguration left exposed. GeminiJack required no permission failure at all. The employee was authorized to see every piece of data Gemini touched. The failure sat in the retrieval and reasoning step, where Gemini treated hidden instructions inside retrieved content as commands to execute rather than text to summarize. Fixing permissions would not have prevented GeminiJack, because permissions were never the broken control. An enterprise can run a flawless permissions audit every quarter and still be exposed to a retrieval-layer attack, which is why both must be treated as separate governance requirements rather than one problem with two names.
3. Did GeminiJack receive a CVE identifier, and is it still exploitable?
No CVE identifier has been reported for GeminiJack in Noma Security's disclosure or in subsequent press coverage. Google confirmed the vulnerability after Noma reported it in June 2025, worked with the researchers through the rest of the year, and shipped a fix that changed how Gemini Enterprise and Vertex AI Search handle retrieval and indexing before the December 2025 public disclosure. Noma Security has not reported evidence that the flaw was exploited in the wild before the fix shipped. The company has pointed to its earlier research on Salesforce Agentforce, a separate prompt injection finding it calls ForcedLeak, as evidence that this is a recurring attack class across agentic AI products rather than an isolated incident.
4. Can data loss prevention tools detect an attack like GeminiJack?
Traditional data loss prevention tooling is built to catch sensitive content leaving through recognizable channels, file uploads, email attachments, and flagged transfers. GeminiJack's exfiltration step used an image request that looked identical to a browser rendering a page correctly, which gave conventional data loss prevention nothing to flag. Closing that gap requires governance applied at the point an AI assistant retrieves and acts on content, inspecting the action itself rather than only the final network transfer. That is a different control than classic DLP, and it must sit at the data-in-use layer where retrieval and reasoning happen, not bolted onto the network perimeter after the fact.
5. What should enterprises do now, beyond waiting for vendor patches?
Audit which AI assistants in the organization retrieve content from connected email, calendar, and document stores, and confirm each one logs what it retrieved and what it did with that content, not just whether the final response succeeded. Apply the same scrutiny to outbound requests an AI assistant generates, including image and resource loads, that would apply to any other data egress channel. Treat retrieval-layer governance as a distinct requirement from permissions management, since GeminiJack proved the two can fail independently of each other. Finally, make sure whatever governance program gets built produces records a compliance team can hand to a regulator directly, not logs an engineer must translate after the fact.
To learn more about retrieval-layer AI risk, schedule a custom demo.